Namaste, I'm Dinesh Timilsena

Data Engineer and AI/ML Engineer

I build scalable data systems, intelligent machine learning solutions, and AI-powered applications that transform complex data into useful decisions.
  • Python
  • SQL
  • Machine Learning
  • Deep Learning
  • Data Engineering
  • LLMs
  • MLOps
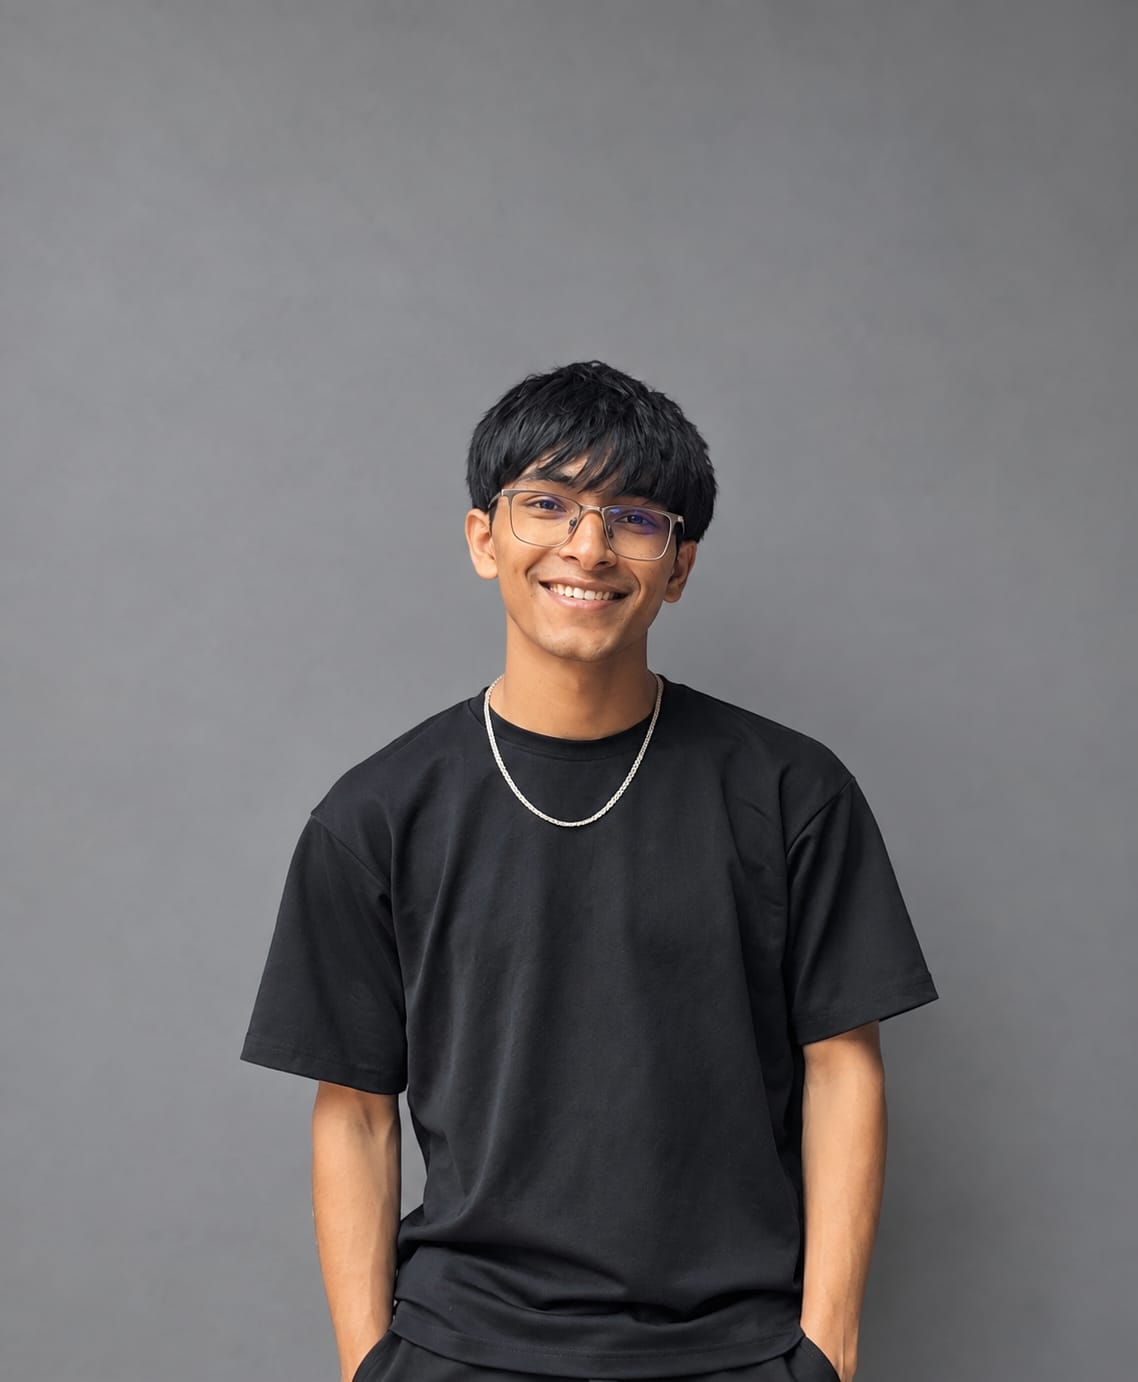
Portrait of Dinesh Timilsena
Python AI/ML PyTorch Spark LLMs
Data & AI
  1. Data
  2. Pipeline
  3. Model
  4. Insight

Introduction

Watch My Introduction

Get to know me, my journey and what I build.
Data Engineering and AI/ML visualization
8 sec Dinesh Timilsena — Data Engineer & AI/ML Engineer

Who I Am

Engineering Data.
Building Intelligence.

I work across the full lifecycle of data from ingesting raw sources and designing reliable pipelines, to training models and shipping AI features that people actually use. I care about systems that are simple, observable and built to scale.

Currently Exploring

  • LLM Engineering
  • MLOps
  • Distributed Systems
  • Cloud Architecture
  • Generative AI
Data

Data Engineering

Building reliable pipelines, ETL/ELT systems, data warehouses and scalable data infrastructure.

Intelligence

AI / Machine Learning

Building predictive models, deep-learning systems and intelligent applications.

Impact

AI Systems

Working with LLMs, RAG, embeddings, vector databases and AI-powered workflows.

Technology Ecosystem

One ecosystem, six domains.

Every tool I use connects back to a purpose. Hover a domain — or filter — to see how it fits.

Programming

  • Python
  • SQL
  • JavaScript

Data Engineering

  • Pandas
  • NumPy
  • Apache Kafka
  • Apache Airflow
  • Apache Spark
  • PostgreSQL
  • ETL / ELT

Data Visualization

  • Power BI
  • Tableau
  • Plotly
  • Matplotlib
DT

Full Stack of Data & AI

27 technologies · 6 domains

Machine Learning

  • Scikit-learn
  • XGBoost
  • PyTorch
  • TensorFlow

AI / LLM

  • LLMs
  • RAG
  • Embeddings
  • Vector Databases
  • LangChain

DevOps / MLOps

  • Docker
  • Git
  • GitHub
  • CI/CD
  • MLflow

How AI Thinks

From a question to an answer
inside a language model.

Type a question and watch it travel through the stages of an LLM: tokens, embeddings, vector space, attention and prediction.

Ready — press “Run model”

  1. 01

    User Question

    Raw text enters the system.

  2. 02

    Tokens

    Text is split into tokens.

  3. 03

    Embeddings

    Each token becomes a vector of numbers.

  4. 04

    Vector Space

    Similar meanings sit close together.

  5. 05

    Transformer

    Self-attention weighs token relationships.

  6. 06

    Prediction

    Probabilities for the next token.

  7. 07

    AI Response

    Tokens are generated one at a time.

Simplified, simulated visualization for learning purposes — numbers are illustrative and not produced by a real model.

Data Engineering

How I Build Data Systems

From raw sources to business decisions every stage designed to be reliable, observable and reproducible.

Stage 01 / 08

Data Sources

Collect raw data from REST APIs, operational databases, event streams and flat files.

    Example stack Python → Airflow → PostgreSQL → Spark → Warehouse → ML → Dashboard

    Selected Work

    Featured Projects

    Real-world systems built with data, AI and engineering. Click any project for the full case study and architecture.

    AI / LLM

    RAG Knowledge Assistant

    A retrieval-augmented assistant that answers questions over private documents with grounded, cited responses.

    Problem
    Knowledge scattered across documents is slow to search.
    Key feature
    Answers grounded in sources with citations.
    • Python
    • LangChain
    • Embeddings
    • Vector DB
    • FastAPI
    GitHub Live Demo

    Data Engineering

    End-to-End ETL Pipeline

    Orchestrated pipeline that ingests multi-source data, transforms it and loads a query-ready warehouse.

    Problem
    Inconsistent raw data, prepared manually.
    Key feature
    Idempotent DAGs with data-quality checks.
    • Airflow
    • Spark
    • PostgreSQL
    • Docker

    Machine Learning

    Production Prediction System

    A trained, evaluated model served behind a validated REST API — built like a product, not a notebook.

    Problem
    Decisions made without predictive signal.
    Key feature
    Versioned model served via API.
    • Scikit-learn
    • XGBoost
    • FastAPI

    Analytics

    Business Intelligence Dashboard

    Interactive KPI dashboard on a clean data model, built for fast, self-serve answers.

    Problem
    No single view of key metrics.
    Key feature
    Drill-down KPIs and filters.
    • SQL
    • Power BI
    • Plotly

    MLOps

    Automated ML Deployment

    CI/CD for models: every push is tested, trained, registered and shipped as a container.

    Problem
    Manual model releases are error-prone.
    Key feature
    Reproducible train → deploy loop.
    • MLflow
    • Docker
    • CI/CD

    AI Data Platform · Capstone

    Unified AI Data Platform

    Ingestion, processing, machine learning and dashboards in one coherent system — the full Data → Intelligence → Impact loop.

    Problem
    Ingestion, ML and reporting live in silos.
    Key feature
    One flow from raw data to ML-driven insight.
    • Airflow
    • Spark
    • PostgreSQL
    • PyTorch
    • Plotly
    GitHub Live Demo

    Experience & Journey

    Learning → Building → Growing

    A path shaped by curiosity and shipped projects. Replace the bracketed fields with your own milestones.

    1. 2025

      Learning

      Foundations in Python, SQL, statistics and data analysis.

      • Python
      • SQL
      • Statistics
    2. 2026

      Building

      First end-to-end projects: data cleaning, dashboards and ML models.

      • Pandas
      • Scikit-learn
      • Power BI
    3. 2026

      Experimenting

      Deep learning, NLP and LLM experiments with embeddings and RAG.

      • PyTorch
      • LangChain
      • Vector DBs
    4. 2026

      Deploying

      Containerized models and automated, scheduled data pipelines.

      • Docker
      • Airflow
      • MLflow
    5. Now

      Growing

      Scaling into distributed systems, cloud architecture and LLM engineering.

      Data Engineer & AIML Engineer

      • Spark
      • Cloud
      • System Design

    Education & Certifications

    Foundations & credentials.

    Nov-2025 — 2029

    Bsc.CSIT

    Tribhuwan University

    Relevant coursework: DSA,DBMS,Operating system, Databases, Statistics & Probablity, AI/ML,Data Mining

    • AI/ML & Data Science

      Apna Collage[World Top Learning Platform] · 2026

    • Python Programming

      Freecodecamp · 2025

    • Google cloud

      Google · 2026

    Skills Matrix

    Capabilities, not percentages.

    Grouped by what I can deliver. Depth is shown honestly as core, working or exploring.

    • Core
    • Working
    • Exploring

    Data

    • SQL & Data Modeling
    • ETL / ELT Design
    • Data Quality & Testing
    • Batch Processing
    • Streaming

    AI

    • Supervised Learning
    • Deep Learning
    • NLP & LLMs
    • RAG Systems
    • Model Evaluation

    Engineering

    • Python Software Design
    • REST APIs
    • Testing & Debugging
    • Version Control
    • System Design

    Cloud

    • Containerization
    • AWS
    • Cloud Storage & Compute
    • Serverless
    • Infrastructure as Code

    Tools

    • Jupyter
    • Airflow
    • Docker
    • MLflow
    • Power BI

    Contact

    Let's Build Something Intelligent.

    Have an idea, project, opportunity or collaboration in mind?

    Data → Intelligence → Impact